Last updated: October 12, 2026
Key Takeaways
- If a brief cannot answer who it is for, what problem it solves, and what it must prove, the draft usually drifts.
- Brief automation works by linking research, classification, and template filling.
- Stable queries tend to need stable structure; competitive queries usually need a flexible one.
- A tool should fit your publishing scale, not just its feature list.
Quick Answer: most teams can automatically generate article briefs in 3 steps, and a simple setup can cut first-draft planning from 30–60 minutes to under 10 minutes. Automatically generating article briefs for an AI writing workflow means turning a keyword, topic, or content gap into a structured brief the model can actually write from. If you want fast drafts that still sound pointed and useful, this is the part to automate first; if your briefs are vague, the output will be vague too.
What should the brief generator actually produce?
It should produce a usable editorial plan, not just a list of keywords. If the brief cannot answer “who is this for, what problem are they solving, and what should the article prove,” then the AI will fill the gaps with generic fluff.
For most workflows, I would have the brief generator output these fields:
- primary search intent
- reader persona or job-to-be-done
- target angle
- recommended H1 and H2s
- key points to cover
- exclusions and pitfalls
- sources to cite
- tone and style notes
- CTA or next action
- internal linking suggestions if your system supports them
A brief that includes only keywords is too thin for an AI model. A brief that includes 20 fields is too heavy for a writer to trust. The sweet spot is usually 8 to 12 fields, with the most important ones filled automatically and the rest optional. In practice, that balance is easier to maintain when the brief generator is tied to your content model, not treated as a one-off prompt.
If you are building this for SEO content, use the brief to decide what kind of article you are making before drafting starts. A “best X for Y” page, a how-to guide, and a comparison post need different structures. If you let the model decide that late, you get a strange hybrid piece.
I would treat the brief as the contract between research and writing, but only with human review where the topic is risky. For legal, medical, or financial content, consult a qualified professional and use the brief as a planning document rather than a final authority.
Quick check: If your current brief could be handed to any writer on any topic, it is too vague.
How do you automate briefs without making them generic?
You automate briefs by chaining research, classification, and template filling. If you skip the classification step, the system will collect data but not know how to shape it into an article plan.
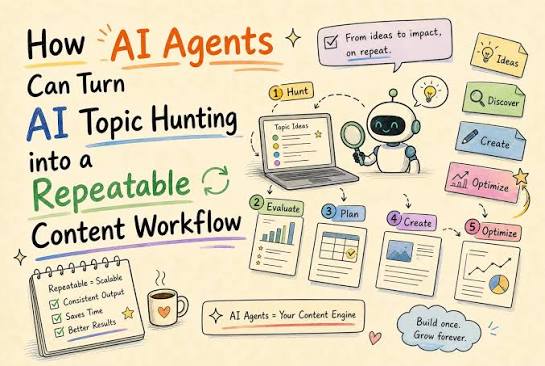
The cleanest workflow is:
- Start with a seed input: a keyword, topic cluster, SERP URL, or customer question.
- Classify intent: informational, commercial, transactional, or navigational.
- Pull live signals from the search results page: recurring headings, featured snippet patterns, People Also Ask questions, and page types ranking now.
- Extract entities and terms that appear across top results, then drop anything irrelevant to the reader’s job.
- Map the topic to a brief template with fixed sections and conditional fields.
- Send the completed brief to the writing model, with constraints on tone, length, and structure.
- Run a quality check that flags missing sections, duplicate angles, or overused terms before drafting begins.
The critical move is step 4. A generic AI brief often mirrors whatever the search results say without deciding what matters. That creates a document full of facts and no point of view. You want the opposite: a clear editorial choice with supporting evidence.
Tools matter here. For SERP and keyword input, teams often use Ahrefs, Semrush, Keywords Everywhere, or Google Search Console data. For automation, Make, Zapier, n8n, or a custom script can pass data from one stage to the next. For the model layer, an API-based workflow with GPT-4-class models or Claude-class models is usually easier to control than a copy-paste process in a chat window. For search intent patterns, Google’s Search Quality Rater Guidelines and Google Search Central both stress matching pages to user needs, not just keywords. You can also use Google Search Console to ground the workflow in queries that already bring impressions and clicks.
The trade-off is control versus speed. Fully automated briefs are fast, but they tend to flatten nuance. Semi-automated briefs are slower, but they let an editor correct the angle before the draft goes off track. If the content has legal, medical, or financial risk, I would not rely on a fully automatic brief without human review.
Quick check: If your workflow has no intent classification and no editorial review, the brief automation is too blunt.
When is a template enough, and when do you need live SERP data?
A template is enough when you write repeatable content for a narrow niche, but live SERP data is necessary when the topic shifts fast or the ranking pages vary a lot. If the query is stable, the structure is stable; if the query is competitive, the structure changes.
Here is the decision point in plain terms:
| Situation | Best Path | Why Other Options Fail |
|---|---|---|
| Low-competition, repeatable topic cluster | Template-driven brief | SERP scraping adds complexity without much gain |
| Competitive SEO keyword | Template + live SERP extraction | A fixed template misses what top pages are emphasizing now |
| News-sensitive or fast-changing topic | Fresh SERP data every run | Old briefs age quickly and mislead the writer |
| Internal knowledge base article | Template from subject-matter rules | Search results may be noisy or irrelevant |
| High-stakes topic | Template + human editor | Pure automation can miss safety, compliance, or nuance |
A template works well when you already know the article type. For example, if every post in a cluster follows the same pattern—problem, causes, steps, pitfalls, FAQ—you can encode that pattern once and reuse it. A template can also carry brand rules such as “avoid hype,” “use short paragraphs,” or “include one comparison table.”
Live SERP data matters when the search results reveal a different intent than the keyword tool suggests. That happens a lot. A keyword may look informational, but the actual top results may all be product pages, listicles, or Reddit threads. If your brief ignores that signal, the AI will write to the keyword, not the market.
The best hybrid setup is often the most practical one, because the template sets the skeleton and live search data fills the muscles. That gives you consistency without turning the content into a clone of every other page.
Quick check: If the ranking pages for your keyword are nearly identical, a template can do most of the work; if they are mixed, you need live SERP input.
Which tools fit this workflow best?
The best tool is the one that matches your scale, not the one with the longest feature list. If you publish 5 articles a month, you do not need a heavy orchestration stack; if you publish 500, you need repeatable automation and logging.
A practical setup can look like this:
- Research layer: Google Search Console, Ahrefs, Semrush, or AlsoAsked for topic signals
- Automation layer: Zapier, Make, n8n, or a custom Python script
- Model layer: OpenAI API, Anthropic API, or another LLM with structured output support
- Storage layer: Airtable, Notion, Google Sheets, or a database
- Review layer: human editor in Google Docs, Notion, or a CMS draft queue
If you want the fastest path from idea to brief, use a no-code stack such as Zapier or Make plus a spreadsheet. If you need branch logic, version control, and better error handling, n8n or a custom script is the safer choice. If the workflow needs to process thousands of briefs, spreadsheets become brittle very quickly. For smaller teams, Google Search Console plus one automation layer is often enough to start.
One thing generic advice misses: the tool choice changes the shape of the brief. Spreadsheet-based workflows tend to favor simple columns and shorter prompts. Script-based workflows can support JSON output, validation rules, and fallback logic. That matters because AI writing systems fail in boring ways: a missing field, a malformed response, a broken API call, or a field that gets overwritten. HubSpot, for example, has reported that companies using automation can save substantial manual effort across repetitive tasks, which is why tool choice matters so much in content operations.
I would also keep your prompt templates in version control. A small change to the brief prompt can alter hundreds of downstream drafts. Without versioning, you cannot tell whether a bad article came from the model, the source data, or the prompt itself.
Quick check: If you need auditability and repeatability, choose a workflow that can store prompt versions and output logs.
How do I build the prompt that creates the brief?
You build it by telling the model what to keep, what to ignore, and what shape the final brief should take. If the prompt only says “make a brief,” the model will improvise structure, and improvised structure is hard to automate.
I would use a prompt that includes:
- the topic or keyword
- the audience
- the search intent
- the article type
- the required sections
- the tone
- the exclusions
- the output format, ideally JSON or a fixed schema
A strong prompt also tells the model what success looks like. For example: “Return a brief with a clear angle, 5 to 7 H2 suggestions, 3 core questions the article must answer, 3 sources to consult, and a short note on what would make the article different from existing results.”
If you want the output to stay machine-readable, ask for JSON with named keys. That makes downstream automation easier, especially if another system is going to turn the brief into a doc, a task, or a draft. A text blob is fine for a single editor. It is messy for a workflow.
Here is the order I would use:
- Define the article type and reader job.
- Give the model the minimum input data from research.
- Tell it exactly which fields to fill.
- Forbid filler such as empty intros, generic benefits, or recycled phrasing.
- Require one clear angle and one clear “do not cover” list.
- Return structured output only.
The biggest mistake is overprompting. A 2,000-word prompt usually signals fear, not precision. Better prompts are shorter and stricter. They tell the model what the brief must contain and what it must not invent. OpenAI and Anthropic both recommend clear, bounded instructions and structured outputs when you need reliable downstream use.
Quick check: If the model’s brief output is hard to parse, your prompt is too loose or the output format is undefined.
What are the edge cases where the normal advice breaks down?
The normal advice breaks down when the topic, source data, or publishing rules are unusual. If you ignore those cases, the automated brief may be technically complete and editorially wrong.
Here are the ones I would watch:
-
Your keyword is ambiguous.
What changes: the search term maps to two or more distinct intents.
What to do instead: add disambiguation logic using the SERP, related queries, or a manual intent override. -
Your niche has very little search volume but high business value.
What changes: keyword tools may give you weak or noisy signals.
What to do instead: brief from sales calls, support tickets, or SME notes, not only from search data. -
Your topic is regulated or sensitive.
What changes: the brief needs guardrails, not just structure.
What to do instead: add a compliance checklist and require human approval before drafting. -
Your content library already has many overlapping articles.
What changes: the brief must prevent cannibalization.
What to do instead: add a field for “distinct angle vs. existing page” and link the closest competing article. -
Your AI system writes in multiple languages.
What changes: literal keyword translation often breaks intent.
What to do instead: brief by local search behavior and native-language query patterns, not by direct translation alone. -
Your source data is inconsistent or stale.
What changes: the model inherits bad assumptions.
What to do instead: timestamp every input and discard old SERP snapshots after a defined window, such as 30 days for fast-moving topics.
This is where many automated systems fail: they assume every topic can be treated the same way. That assumption is risky, because some topics need tighter controls, and some need a human editor. A clean automation pipeline still needs escape hatches for judgment.
Quick check: If any of your topics are ambiguous, regulated, multilingual, or tightly overlapping, you need exception handling in the brief workflow.
What does a good automated brief look like in practice?
A good automated brief gives the writer one clear path and one clear boundary. If the brief cannot help someone draft the article without guessing, it is not ready.
At minimum, I want the brief to include:
- the reader’s problem in one sentence
- the article’s angle in one sentence
- the article type
- the 5 to 7 main sections
- the must-answer questions
- the sources or standards to consult
- the “do not cover” list
- the tone and level of detail
That is enough for an AI writer to produce a credible first draft and enough for a human editor to spot drift quickly. It is also enough to keep the workflow from turning into a content factory that outputs sameness.
The trade-off is obvious: the more automated the brief, the more discipline you need in your templates and prompts. If your source data is weak, automation accelerates mistakes. If your source data is solid, automation saves hours of repetitive planning. Ahrefs and Semrush data can help here, but only if you treat them as signals rather than instructions.
My rule is simple. Automate the repetitive parts of briefing, but keep the judgment calls visible. That means intent, angle, exclusions, and review rules should stay explicit. Those are the places where the brief earns its keep.
Quick check: If an editor can glance at the brief and predict the draft’s structure, the automation is doing real work.
FAQ
Can I generate article briefs from a keyword list alone?
Yes, but only for simple topics. If the keyword is competitive or ambiguous, add SERP data, intent classification, and an exclusion list.
Do I need JSON output for brief automation?
No, but JSON is easier to validate and move between tools. If a human is the only reader, plain text is fine.
Should the AI also write the article after it makes the brief?
It can, but I would separate the steps when quality matters. A brief is planning; a draft is execution.
What is the biggest failure mode in automated briefs?
Generic structure with no editorial angle. The brief looks complete, but it does not tell the writer what makes the piece different.
Is full automation a good idea for every content team?
No. It fits high-volume, repeatable work best. For regulated or high-stakes topics, keep a human in the loop.
Drafted with AI; not yet reviewed by a person.